I built an app and it cost almost $40
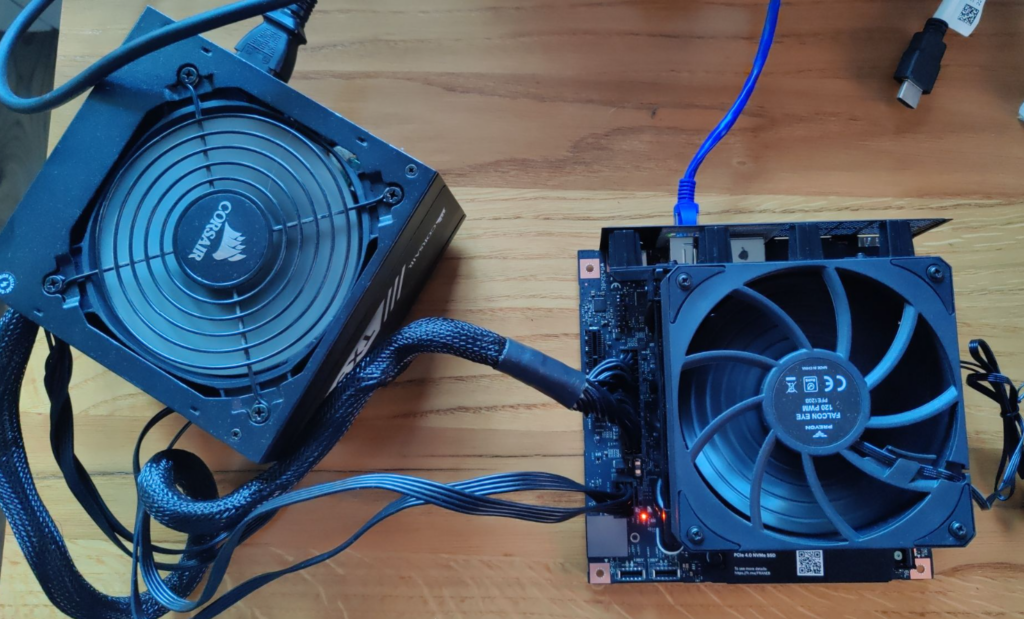
I posted already about me selfhosting LLM models. Right now I have two devices:
- Framework Desktop
- Custom Ryzen Threadripper server with R9700 32GB GPU
Both are decent with llama.cpp. The biggest issue is prefill times.
I have from work subscription for Claude and Codex which I tested too for last couple of months. It is OK but lack of thinking traces really hurt to keep up with what models are doing.