InternetException

Posts

Using Junie agent CLI with local model

· 573 words · ~2 min read · in AI

#coding agents #source generators

Jet Brains have their own coding agent. Since I am already using Rider and all coding agents are pretty slow and inefficient with what they do I wanted to test if Junie have better integrations with IDE which would make things much faster.

For example if you will have following unused namespace in Rider.
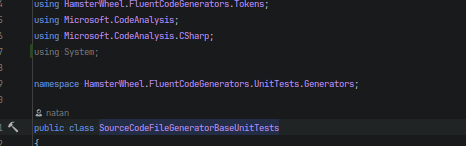
Removing it all cleaning all unused namespaces in entire project or even entire solution is just few clicks away. Or key strokes.

Read the whole thing →

AI agent critique of itself

· 479 words · ~2 min read · in AI

#coding agents #self-hosting

I like to self-host my own services. I have my own email server. I have my own cloud storage and sync and backup. I want to have this secure and safe while having my data private.

But I need to learn and be up to date with current technology.

I decided to use Junie with my own, self hosted models that I run on my own hardware . In the docs they say it can be run on top your own custom provider and model. But it does not work with Rider plugin. You are limited to their own limited list of models.

Read the whole thing →

Testing Qwen 3.6

· 771 words · ~3 min read · updated · in AI

#Qwen #Nanobot

Today I noticed that new version of Qwen was realesed . Only 35B-A3B for now but this is the same size of Qwen I was using previously. Usually (as with every other software) it is better to wait few weeks for fixes, in this case for re uploads of the model, that is done after testing/template adjustments, but it is not a problem to do few tests. I decided to give it a spin. I added it to my llama swap instance and started it up.

Read the whole thing →

Bonding Network interfaces in Debian Forky

· 1345 words · ~6 min read · updated · in debian, linux, DevOps

#network bonding #GPU

I am experimenting lately on with Nanobot and running self hosted language models on Desktop Framework.

I was trying to run lately Qwen 3.5 397B model on this small PC and it was a bit hard because I just do not have enough disk space on it. I bought just small NVMe SSD disk. With current prices, I planned to use disk space on other server I have at my hope as storage

Read the whole thing →

Running Qwen 3.5 397B on Desktop Framework

· 267 words · ~1 min read · in AI, Hardware

#Qwen #Desktop Framework #llama.cpp

Today I finally was able to download and run largest Qwen 3.5 model. I downloaded the smallest quant even if a bit bigger probably would fit too, but I want to run also few smaller models at the same time, so 107GB for UD-IQ1_M is the biggest I was able to spare.

I downloaded and was able to run it with llama.cpp with the following command:

./llama-server \
   -hf unsloth/Qwen3.5-397B-A17B-GGUF:UD-IQ1_M\
   --ctx-size 32000 \
   --no-warmup \
   --no-mmap \
   --flash-attn on \
   --n-gpu-layers 1 \
   --host 0.0.0.0\
   --port $1 \
   --direct-io \
   --jinja --chat-template-file /data/apps/vllm/qwen3_nonthinking.jinja

My intention was to test it with nanobot to see if this will be capable agent for my AI assistant.

Read the whole thing →

My first PR to Nanobot

· 346 words · ~1 min read · in AI

#Nanobot

I am blogging last few weeks about my new aventure with nanobot. I am running model for that little assistant of mine on Desktop Framework motherboard I bought couple of days ago.

Few days ago I was working on my own fork of nanobot. I was not happy how few things are not entirely correctly implemented in this project. For example command support in Matrix channel. I created PR for that one here . Unfortunately it was not merged yet. I am not sure why. Maybe it is mising few unit tests.

Read the whole thing →

Swapping vLLM to Llama.cpp

· 1701 words · ~8 min read · updated · in AI

#vLLM #llama.cpp #Qwen #GPU

Yesterday I posted about vLLM being nice but optimized for different usage I am being really interested in . I commented on Llama Swap GH issue asking for help my problem of vLLM being shutdown before it actually started. During writing that comment I was thinking about Llama.cpp and it inability to run Qwen 3.5. It was at the beginning of March when I started (again) experimenting with LLMs. I tried to run Qwen models with release version of Llama.cpp and it was failing with ‘model architecture of Qwen3 is not found’ (or something like that; I do not really remember). Because of that I switched to using vLLM, even if it could not run Qwen 3.5, it could run Qwen 3 just fine from the docker image. Sglang seemed like not a good choice for my needs.

Read the whole thing →

vLLM is fast but kind of slow

· 726 words · ~3 min read · updated · in AI

#vLLM #Qwen #Ryzen AI Max #GPU

I was using vLLM to run my AI assistant models for few weeks now. It is quite nice, production ready framework that have few bugs . ROCm support and by extent Strix Halo support is quite nice, even if AMD GPU docker image does not work on Strix Halo without aiter in custom version.

Interference speeds are quite nice. You can get 20-30t/s out of new AMD APU. Which is totally usable. Here is sample test I done on this device via LLM API Throughput Benchmark:

Read the whole thing →

Integrating my AI assistant with StartPage

· 673 words · ~3 min read · in AI

#design patterns

Today I was fixing an issue with my assistant having a hard time accessing web search . I fixed that but I was not entirelly satisfied with the result. Browsh is great for that used but I am using StartPage on my PC and on my phone. Ability to see similar or even the same web search result for me and my assistant would be great.

How hard it can be to actually fetch the result od search via CLI? Actually it is not that hard. I was able to figurę it out though it requires very specific set od parameters, headers being sent to very specific address.

Read the whole thing →

Teaching my AI assistant to surf the web part 2

· 737 words · ~3 min read · in AI

#Qwen #Nanobot #GPU

Few days ago I thought my assistant to do web search via Browsh and Duck Duck Go. It was working for some time with small problems, like for example I changed host name of the machine hosting nanobot and forget to adjust the host name in skill URL. Another small pain point is that sometimes returns timeout instead of web page content and not falls back to Brave Search API, and since I do not like that service, there is no API key and it falls back to DDG via python code. So it is mostly slow but I am still happy with that.

Read the whole thing →

Desktop Framework AI assitant part 3

· 450 words · ~2 min read · in AI, Hardware

#Desktop Framework #vLLM #Qwen #Nanobot

Recently I started playing with Nanobot which is a bit like OpenClaw but, in my opinion much better since it is small and simple and have native integration with custom OpenAI APIs providers. I decided to use vLLM because I wanted to use Qwen 3.5 because according to my quick reaserach it is pretty good in such agentic usage and Qwen models are built with integration with SgLang and vLLM frameworks in mind. Also AMD is testing their own drivers and libraries, ROCm on docker images with SgLang and vLLM and Desktop Framework is AMD APU. So all of it since like a good idea since I decided to go with Strix Halo unifies memory architecture for my AI assistant. I bought Desktop Framework motherboard and played with it a little to test models performance on ROCm inside the docker. It was not blazing fast but enough to actually have working solution.

Read the whole thing →

Adding voice recognition to my AI assistant

· 2507 words · ~12 min read · updated · in AI

#voice recognition #vLLM #llama.cpp #Qwen

It is amazing how time flies… I am living at my current house already 9 years almost. I did put up a fence around the house in 2019. Next year I installed metal gate with automation and was working on a way to make it more ‘smart’. My first attempt was to have small raspberry Pi connected via some metal wires and solid relays to the gate electrical engine. It is working like that till now.

Read the whole thing →

Running AI assistant on Qwen 3.5

· 1233 words · ~6 min read · updated · in AI

#Qwen #vLLM #Ubuntu

I did make mistake installing my favorite Debian Linux distribution on Desktop Framework PC I am using to run my LLM models. Probably some hacking during installing vLLM and all libraries and drivers and I would be able to make it work. But is it really worth it? I think it was not. So I switched to Ubuntu and I am running Qwen 3.5 second day now.

For now I can say that I am very happy. It seems to be able to reason much better than its predecessor Qwen 3. It have pretty good vision capabilities. It is able to fix its own mistakes, which makes its usage much easier.

Read the whole thing →

Integrating my AI assistant with pyLoad

· 1256 words · ~6 min read · updated · in AI

#Qwen #API design #Debian

I am using pyLoad download manager for quite some time now. Previously when I was running windows server I was using JDownloader. I think it was better in few things, for example it was able to automatically name a package based on the name of the file from the link. So if I would be trying to download https://cdimage.debian.org/debian-cd/current/amd64/iso-cd/debian-13.4.0-amd64-netinst.iso, it would automatically name a package ‘debian-13.4.0-amd64-netinst.iso’. Folder with downloaded file would be named the same too. Much more convenient. If I would drop multiple links for the same file it would be downloading them in parallel, downloading them much quicker. Though with current speeds in average home maybe this is not necessary anymore. It had better UI, in my opinion, but maybe I was more accustomed to windows desktop then; certainly it was better to have single view instead of 3 views like in pyLoad:

Read the whole thing →

Running Qwen 3.5 on AMD Ryzen AI Max+ 395

· 140 words · ~1 min read · updated · in AI, Hardware

#Qwen #Ryzen AI Max #vLLM #Nanobot

I bough lately Desktop Framework with intention of running Qwen 3.5 as model for my AI assistant on Nanobot . At first I could not run this model on this hardware for some weird bug in one of the libraries. I explained why and how I fixed it here . In this post I will just put the list of packages that I used to run Qwen finally and vLLM command switches and parameters.

Read the whole thing →